2018 Hiver Q2
NYU Lecture is really useful NYU Deep Learning(2020年の講義公式サイト)
6.

(a).
Describe a scheme to estimate the vector of parameters θ to maximize the log likelihood of the N training examples.
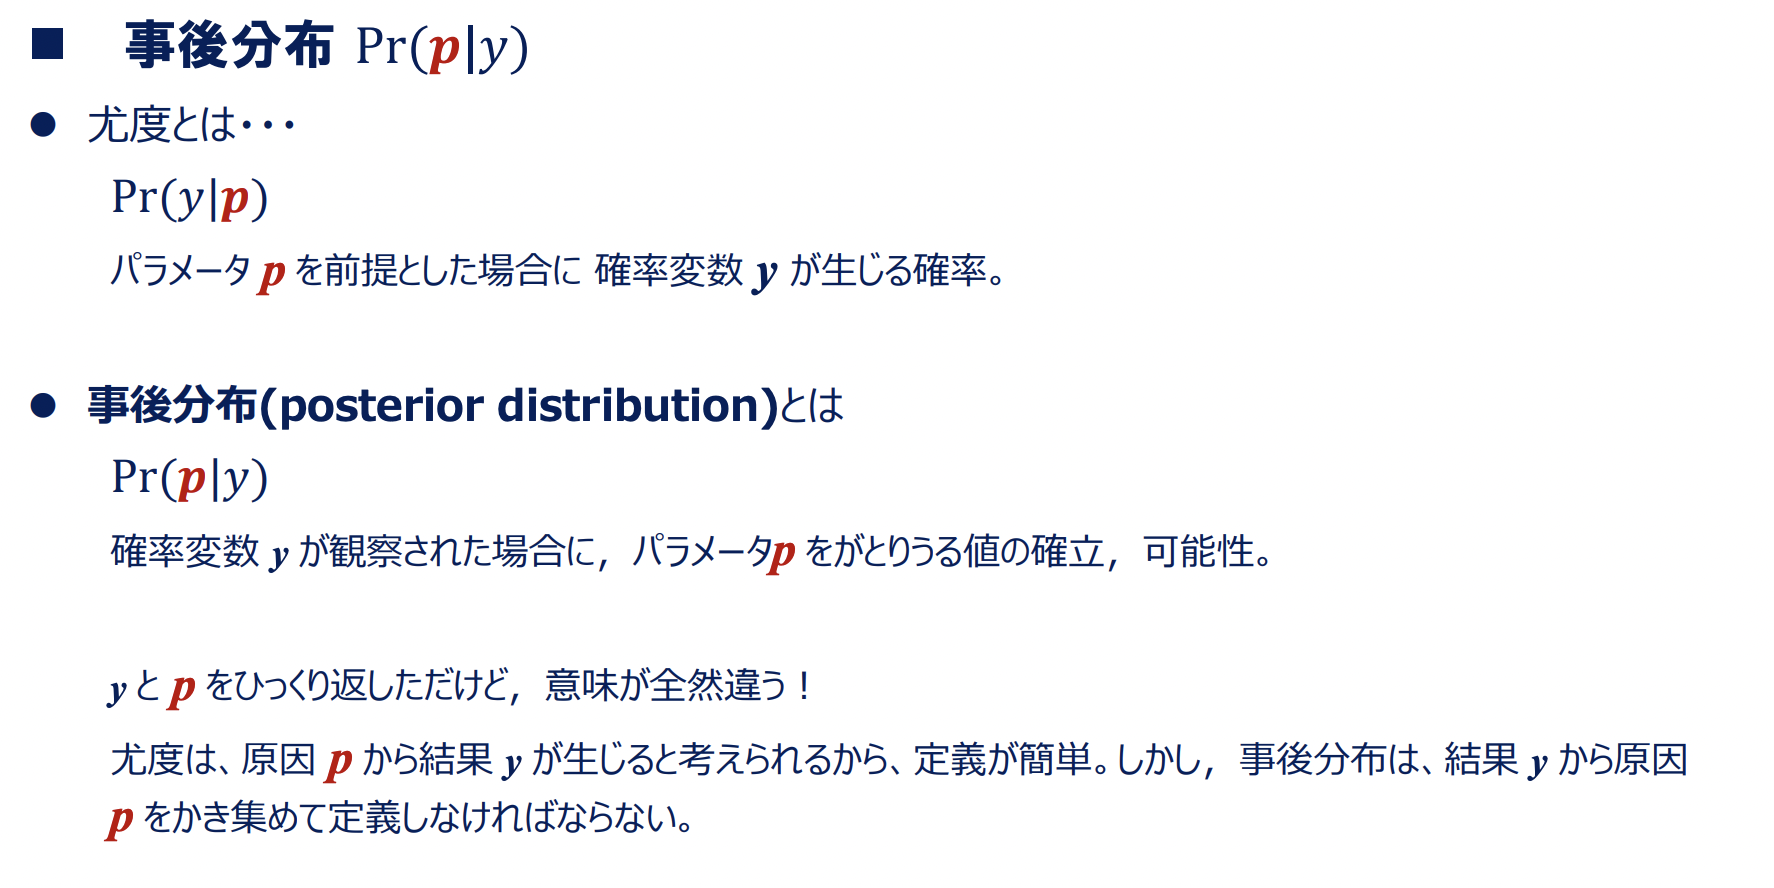
識別モデル:データに対するクラスの条件付き確率(事後確率)p(Ck|x)を直接モデル化するのが識別モデル
生成モデル:p(Ck|x) = p(x|Ck)p(Ck)/p(x) の右辺をモデル化する

(b).
Describe how the scheme should be modified if you are given a prior distribution on the model parameters, p(θ).

(c).
Describe the difference between a maximum a posteriori prediction and a full Bayesian prediction. Be as specific as possible.
ベイズ推論の枠組みで、デルタ関数を用いてMAPを記述する
- Answer
- MAP推定と最尤推定
- 変分ベイズ詳解&Python実装。最尤推定/MAP推定との比較まで。 とてもわかりやすい
- 変分推論の理論 詳し
- く変分ベイズの話が書いてある
- Delta Function
(d).

最尤法で求めた分散は真の分散を過小評価している
7.


- [DL輪読会]近年のエネルギーベースモデルの進展: まずはこの資料から
- Energy-Based Model:ノイズを復元して生成モデルを学習する
- エネルギーベースモデルの物理学:物理学を使用してエネルギーベースモデルを理解する詳しく書いてるが僕の理解が怪しい
- Energy-Based GaN by Bengio

